
 latent
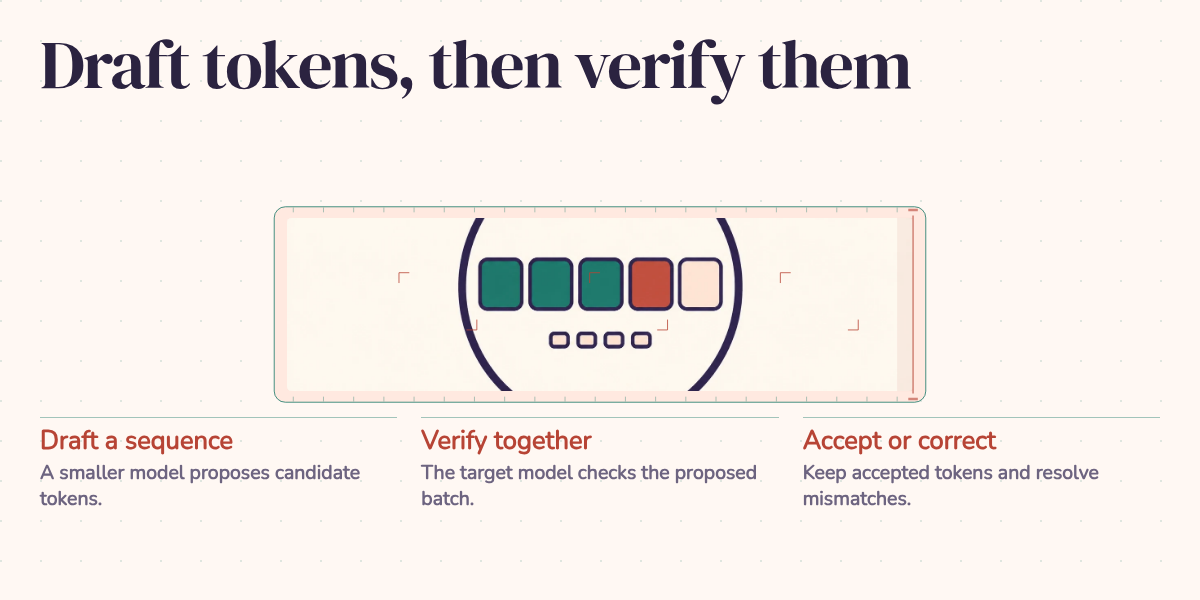
A small model drafts five tokens: A, B, C, D, E. A larger model checks the whole proposal, accepts A through C, rejects D, and supplies a corrected fourth token. Four tokens move into the answer after one pass through the expensive model.
That's the appeal of speculative decoding. The small model does cheap advance work; the large model remains responsible for what reaches the reader. The interesting question is how to keep the large model's output distribution intact while doing fewer sequential passes, and when that actually makes a response faster.
Speculative decoding flow:

1. Draft model generates: [A, B, C, D, E]  (K=5 draft tokens, fast)

2. Target model verifies all 5 in ONE forward pass

3. Acceptance check:
   Position 1: A ✓ (accepted)
   Position 2: B ✓ (accepted)
   Position 3: C ✓ (accepted)
   Position 4: D ✗ (rejected, sample D' from the correction distribution)
   Position 5: E   (discarded, after rejection point)

Result: [A, B, C, D'], 4 tokens from one target model forward pass
This is an illustrative token sequence, not a benchmark. It shows the unit of progress: several committed tokens per verification pass. The time spent drafting still belongs on the bill.
Why checking ahead is possible
An autoregressive model generates text one token at a time. It computes probabilities for the next token, samples one, appends it to the context, and repeats. Token 5 depends on token 4, so ordinary generation has to wait.
Standard autoregressive decoding:

Token 1 → [Full forward pass] → Token 2 → [Full forward pass] → Token 3 → ...

Each step: read model weights from memory, compute the next token.
Small-batch decoding can leave much of the GPU's arithmetic capacity unused.
For a large dense model serving a small batch, repeatedly reading the weights can take more time than the arithmetic itself. This is what "memory-bandwidth bound" means: the GPU can calculate faster than it can fetch the values it needs. Larger batches can reuse those weights across more requests and change the bottleneck.
A draft gives the target model something ordinary generation lacks: candidate tokens at all the positions it needs to check. A transformer can calculate their conditional probabilities in parallel, with each position seeing only the prefix before it. Verification still respects the sequence; it just evaluates a proposed sequence in a batch.
When spare compute is available, checking a short block can cost much less than generating those tokens through separate target passes. It does involve more work than checking one position. Whether the hardware absorbs that extra work cheaply is part of the performance question.
The correction that keeps the target in charge
Acceptance doesn't mean the two models picked the same favorite word. In the standard probabilistic algorithm, let be the draft's probability of token and the target's probability, both conditioned on the same prefix. A sampled draft token is accepted with probability
If the draft proposes a token more often than the target would, the ratio trims that excess. If the target gives it at least as much probability, it passes. This is the acceptance step from Leviathan, Kalman, and Matias's speculative decoding algorithm.
import random

# Acceptance decision only; rejection correction is also required.
def accept_token(draft_prob, target_prob):
    """The proposed token was sampled from q, so draft_prob must be positive."""
    if draft_prob <= 0:
        raise ValueError("A sampled draft token must have positive probability")
    if target_prob >= draft_prob:
        return True
    return random.random() < (target_prob / draft_prob)
After the first rejection, discard the rest of the draft. The replacement must come from the normalized positive difference between target and draft probabilities:
That correction fills the probability mass the accepted proposals haven't supplied. Sampling directly from at this point would generally bias the result. If every draft token passes, the target supplies one additional token from its distribution after the full accepted prefix. The speculative sampling paper by Chen and colleagues describes this distribution-preserving procedure.
A tiny example makes the correction easier to see. Suppose the only tokens are red and blue. The draft proposes them with probabilities 0.8 and 0.2; the target wants 0.5 and 0.5. Red passes with probability 0.5/0.8, so accepted red proposals contribute 0.5 overall. Blue always passes, contributing 0.2. The remaining 0.3 consists of rejected red proposals, and the correction sends all of it to blue. The result is exactly the target's 50/50 split.
Under the algorithm's assumptions, that equality holds at each position and therefore for generated sequences. It means the same probability distribution, not necessarily the same sampled sentence on two runs. Hardware precision and the chosen implementation still matter; vLLM documents its lossless guarantees and their limits.
When accepted tokens repay the work
With draft tokens, a successful round can produce at most tokens, including the target's extra token. In a simplified model with a constant independent acceptance probability at each position, the expected number of tokens per round is
For and , that is , or about 3.69 tokens per target pass. At , the limit is six. Actual acceptance varies with the prefix, so this geometric series is a useful model rather than a guarantee for every request.
To turn that into an estimated speedup, account for the entire round. Let be the time for one ordinary target decoding step, one draft step, and the verification pass. Ignoring other overhead for this toy calculation,
Suppose a draft step costs one tenth of a target step and verification costs one target step. Five draft steps plus verification cost 1.5 target steps. The estimated speedup is then 3.68928/1.5, about 2.46x. If verification instead costs two target steps, it falls to about 1.48x. The accepted-token count hasn't changed; the economics have.
Published results show that the opportunity is real. Leviathan and colleagues reported 2-3x acceleration on T5-XXL against their standard T5X baseline. Chen and colleagues reported 2-2.5x decoding speedup with the 70-billion-parameter Chinchilla model in a distributed setup. Those are results for particular models, workloads, and implementations, not a default multiplier for enabling the feature.
The practical tradeoff follows from that accounting. A longer draft offers more tokens but wastes more work after an early rejection. A more capable draft may improve acceptance while costing too much to run. Predictable passages, including repeated code, can be good candidates; what matters is how closely this draft tracks this target on the requests being served.
Short answers leave fewer decoding rounds over which to recover overhead, and prompt processing can dominate total response time. Large batches may already occupy the compute capacity that verification would use. Temperature also changes the distributions being compared, but higher temperature alone doesn't determine their overlap or the acceptance rate. Measure with the sampling settings users actually need.
Choosing who does the drafting
A smaller model from the same family is a straightforward starting point, such as Llama 3 8B drafting for Llama 3 70B. A student distilled from the target can also be useful because its training encourages imitation. Neither family membership nor distillation guarantees the best speedup: compatibility, acceptance, and draft cost all need checking.
Other approaches change how the proposal is made:
- Medusa adds prediction heads and checks candidate continuations using tree attention. Its training and acceptance variants have different guarantees; "speculative" alone doesn't establish exact distribution preservation.
- EAGLE predicts future internal features using a lightweight network and token information, then maps those features to candidate tokens. It reuses information the target has already computed.
- Staged speculative decoding adds another speculation stage so a cheaper model can help a larger draft model prepare candidates for the target.
- Self-speculative decoding can draft by skipping some target-model layers, then verify with the full model. The cited method needs no additional training or auxiliary model.
These approaches all try to make useful proposals cheaper. They do not share one universal acceptance rate or deployment cost.
Trying it in a serving framework
vLLM exposes draft-model configuration through speculative_config. The Llama pair below proposes five tokens at a time, using the documented configuration interface:
# vLLM with speculative decoding
from vllm import LLM, SamplingParams

llm = LLM(
    model="meta-llama/Llama-3-70B-Instruct",
    speculative_config={
        "method": "draft_model",
        "model": "meta-llama/Llama-3-8B-Instruct",
        "num_speculative_tokens": 5,
    },
)

output = llm.generate("Explain speculative decoding", SamplingParams(max_tokens=512))
This is a configuration example, not a measured deployment. It assumes access to the model weights, a compatible vLLM release, and enough hardware for both models and their caches. Hardware-specific parallelism and memory settings still need to be supplied where necessary.
Other serving stacks offer their own implementations. Hugging Face TGI documents Medusa and n-gram speculation. llama.cpp provides a speculative decoding example for local inference, and TensorRT-LLM supports speculative sampling. Choose the supported method for the model and hardware, then test it alongside the batching and cache settings already in use.
What would justify enabling it?
I would compare speculation on and off using the same prompts, output lengths, sampling settings, and production-like concurrency. Record accepted tokens per round, time between output tokens, total response latency, memory use, and throughput. Include short and long responses. A faster single request can still be a poor trade if the extra model consumes memory needed to serve other requests.
Cost needs its own measurement. Halving decoding time doesn't automatically halve the bill: prompt processing, idle capacity, draft resources, and the number of concurrent users remain part of the service.
The five-token example explains why speculation can work. The expensive model checks a proposal and commits several tokens while retaining control of the distribution. Enable it when those accepted tokens repay the drafting, verification, and memory costs on your workload. That is a concrete performance gain you can defend, with the target model's sampling behavior preserved by the correct algorithm.